Masked Attention
Definition
Let three matrices $\mathbf{Q} \in M^{d_{k} \times n}$, $\mathbf{K} \in M^{d_{k} \times m}$, $\mathbf{V} \in M^{d_{v} \times m}$, called the query, key, and value respectively, be given. A matrix $\mathbf{M} \in M^{m \times n}$ whose entries are $0$ or $-\infty$ is called a mask, and the function defined as follows is called masked attention.
$$ \operatorname{MaskedAttention}(\mathbf{Q}, \mathbf{K}, \mathbf{V}) := \mathbf{V} \operatorname{Softmax} \left( \frac{\mathbf{K}^{\mathsf{T}} \mathbf{Q}}{\sqrt{d_{k}}} + \mathbf{M} \right) \tag{1} $$
Here $\operatorname{Softmax}$ denotes the function that, for a given matrix $\mathbf{X} = \begin{bmatrix} \mathbf{x}_{1} & \cdots & \mathbf{x}_{N}\end{bmatrix}$, applies the softmax $\operatorname{softmax}$ to each column vector so that each column sums to $1$.
$$ \operatorname{Softmax}(\mathbf{X}) := \begin{bmatrix} \underset{\vert}{\overset{\vert}{\operatorname{softmax}(\mathbf{x}_{1})}} & \cdots & \underset{\vert}{\overset{\vert}{\operatorname{softmax}(\mathbf{x}_{N})}} \end{bmatrix} $$
Explanation
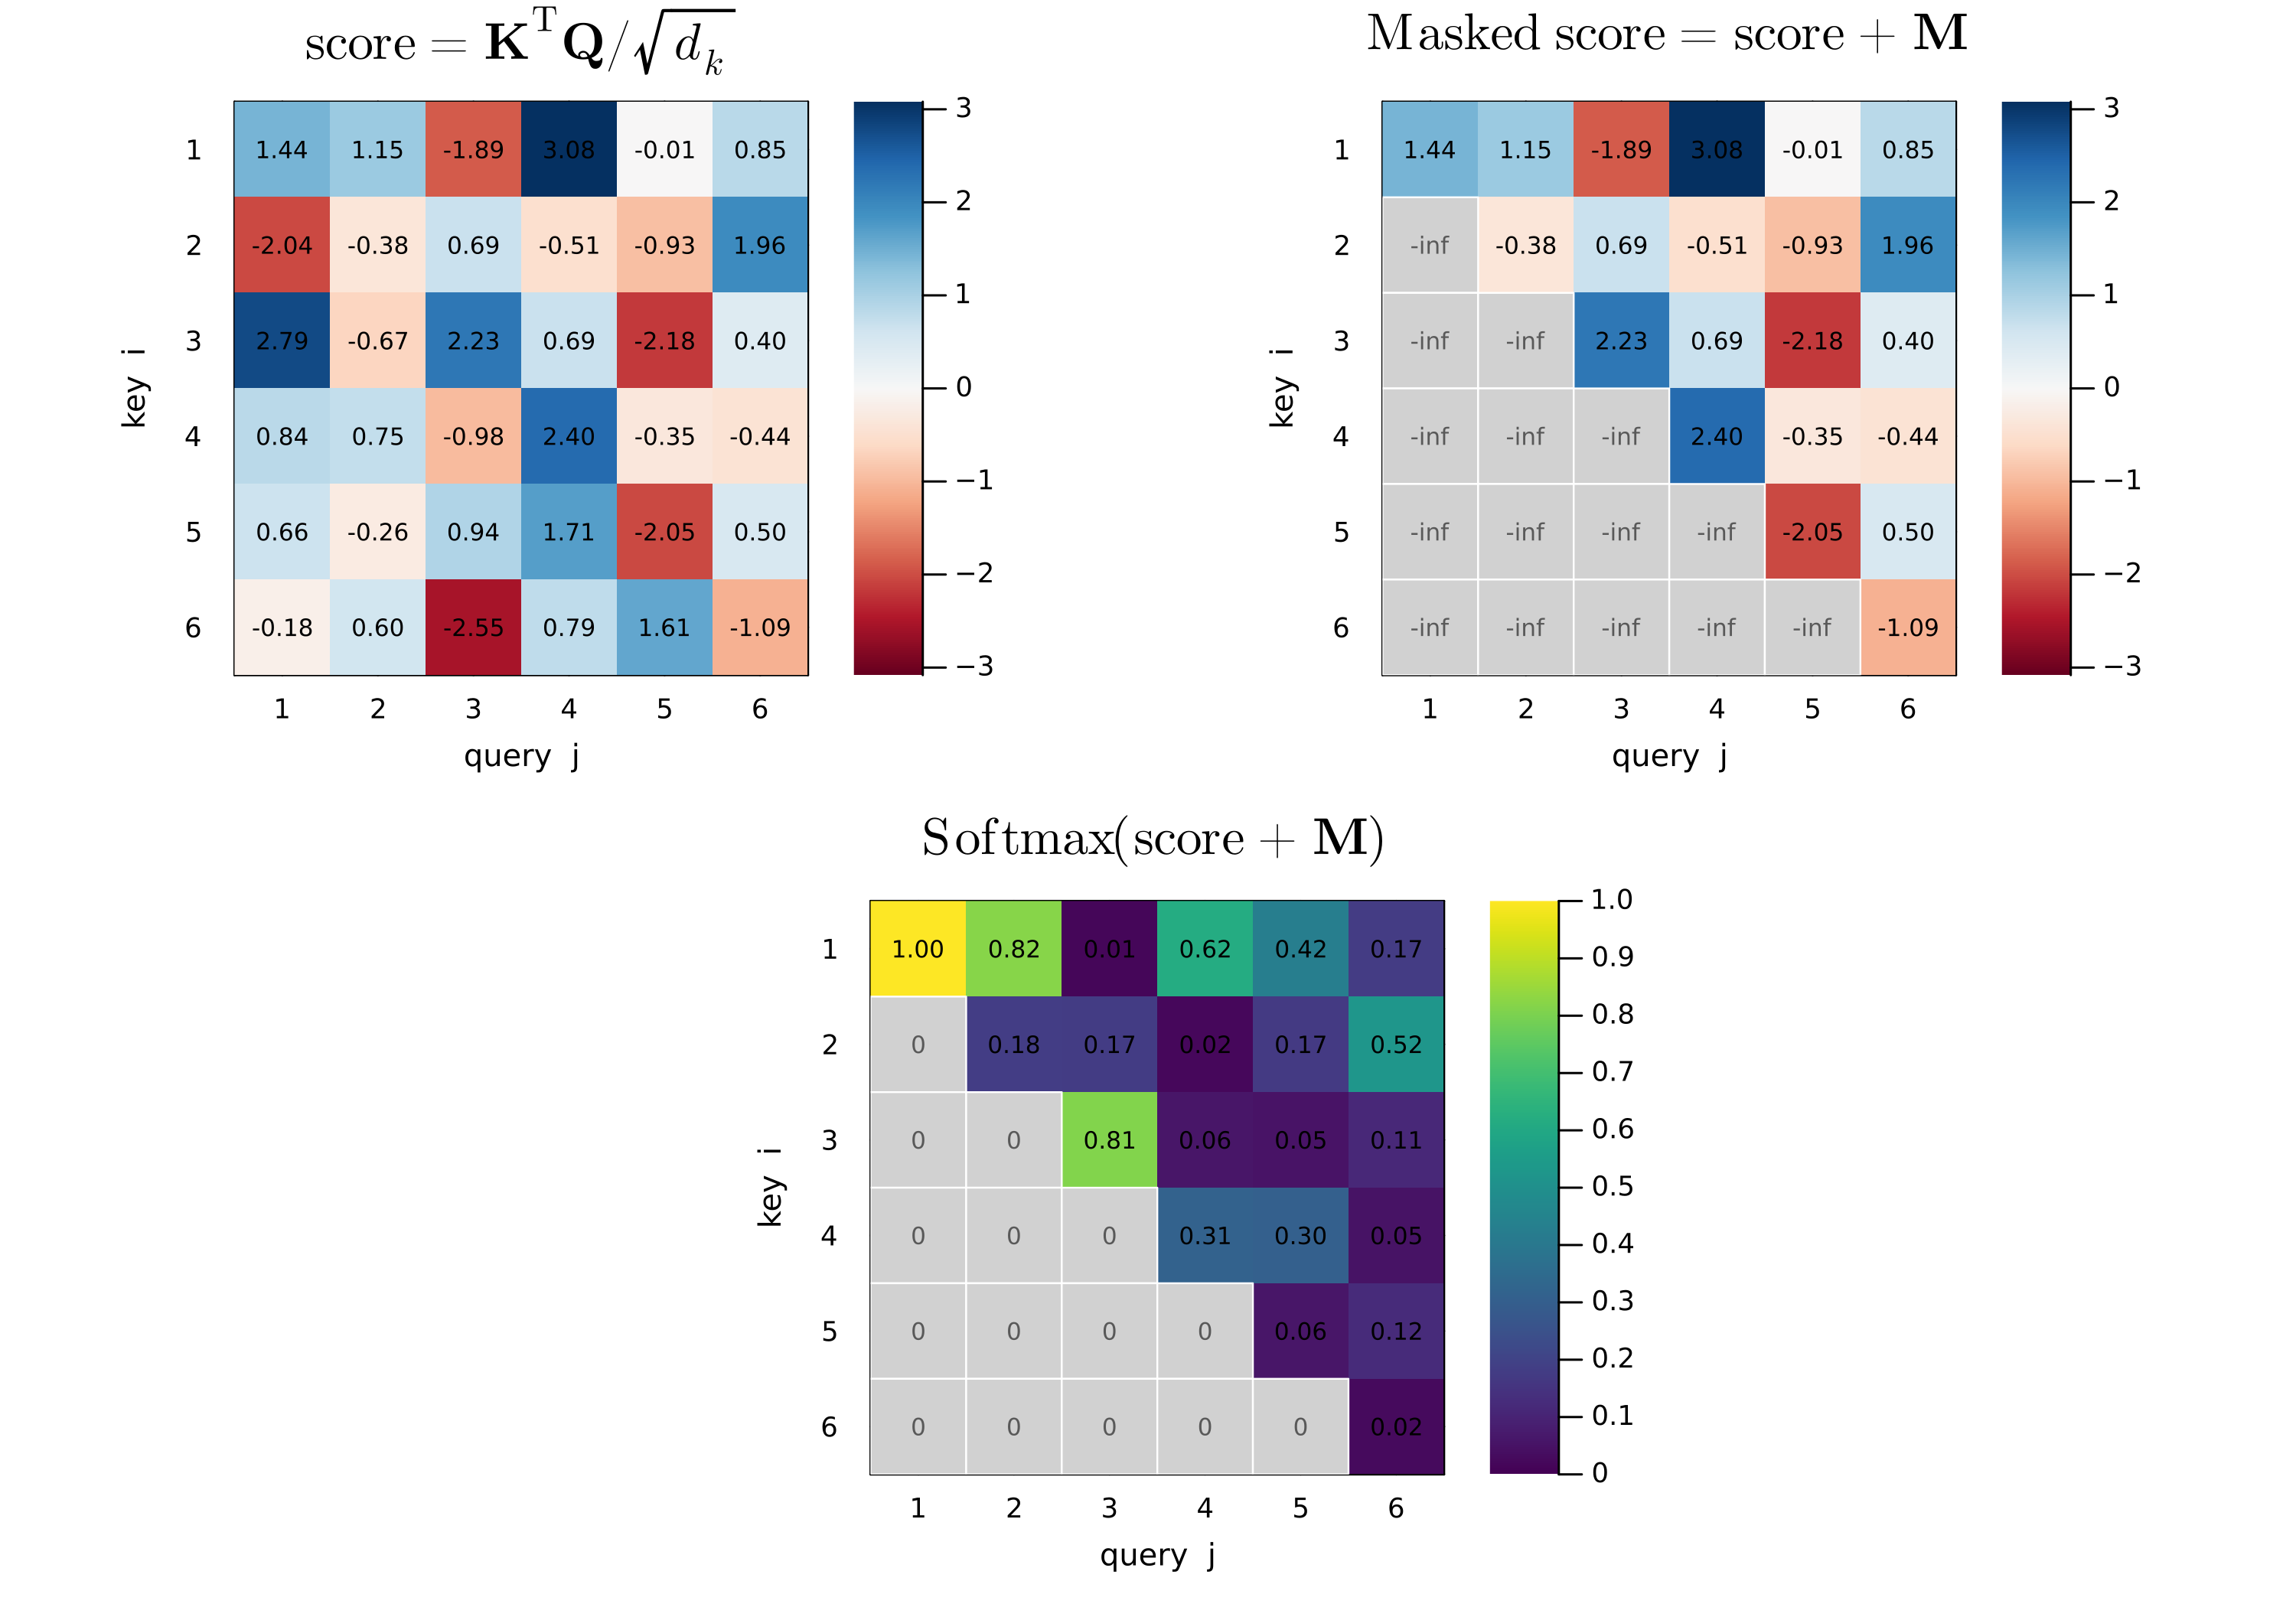
That $[\mathbf{M}]_{ij} = 0$ means that $\operatorname{score}(\mathbf{k}_{i}, \mathbf{q}_{j})$ is left as it is, and that $[\mathbf{M}]_{ij} = -\infty$ means that the value of $\operatorname{score}(\mathbf{k}_{i}, \mathbf{q}_{j})$ is corrected and forced to $-\infty$. By the definition of the softmax, $\operatorname{softmax}(-\infty) = 0$, so the masked entries end up with an attention probability of exactly $0$ after passing through the softmax. In other words, masking is a device that forcibly hides certain keys/values from a query.
In the Transformer paper, the first sublayer of the decoder uses a causal mask that lets a query see only itself and the keys before it. That is, whether the $i$th query can refer to the $j$th key is determined by whether $i \gt j$. Defining this as a function gives the following.
$$ \begin{bmatrix} \operatorname{Mask}(\mathbf{K}^{\mathsf{T}} \mathbf{Q}/ \sqrt{d_{k}}) \end{bmatrix}_{ij} = \begin{cases} -\infty & i \gt j \\ \mathbf{k}_{i}^{\mathsf{T}} \mathbf{q}_{j} / \sqrt{d_{k}} & i \le j \end{cases} $$
$$ \operatorname{MaskedAttention}(\mathbf{Q}, \mathbf{K}, \mathbf{V}) := \mathbf{V} \operatorname{Softmax} \circ \operatorname{Mask} \left( \frac{\mathbf{K}^{\mathsf{T}} \mathbf{Q}}{\sqrt{d_{k}}} \right) $$
Meanwhile, in actual implementations, it is usual to add a very large negative number such as $-10^{9}$ instead of $-\infty$.